Before retrying, check whether the action happened
Recover from an ambiguous timeout without creating a duplicate effect.
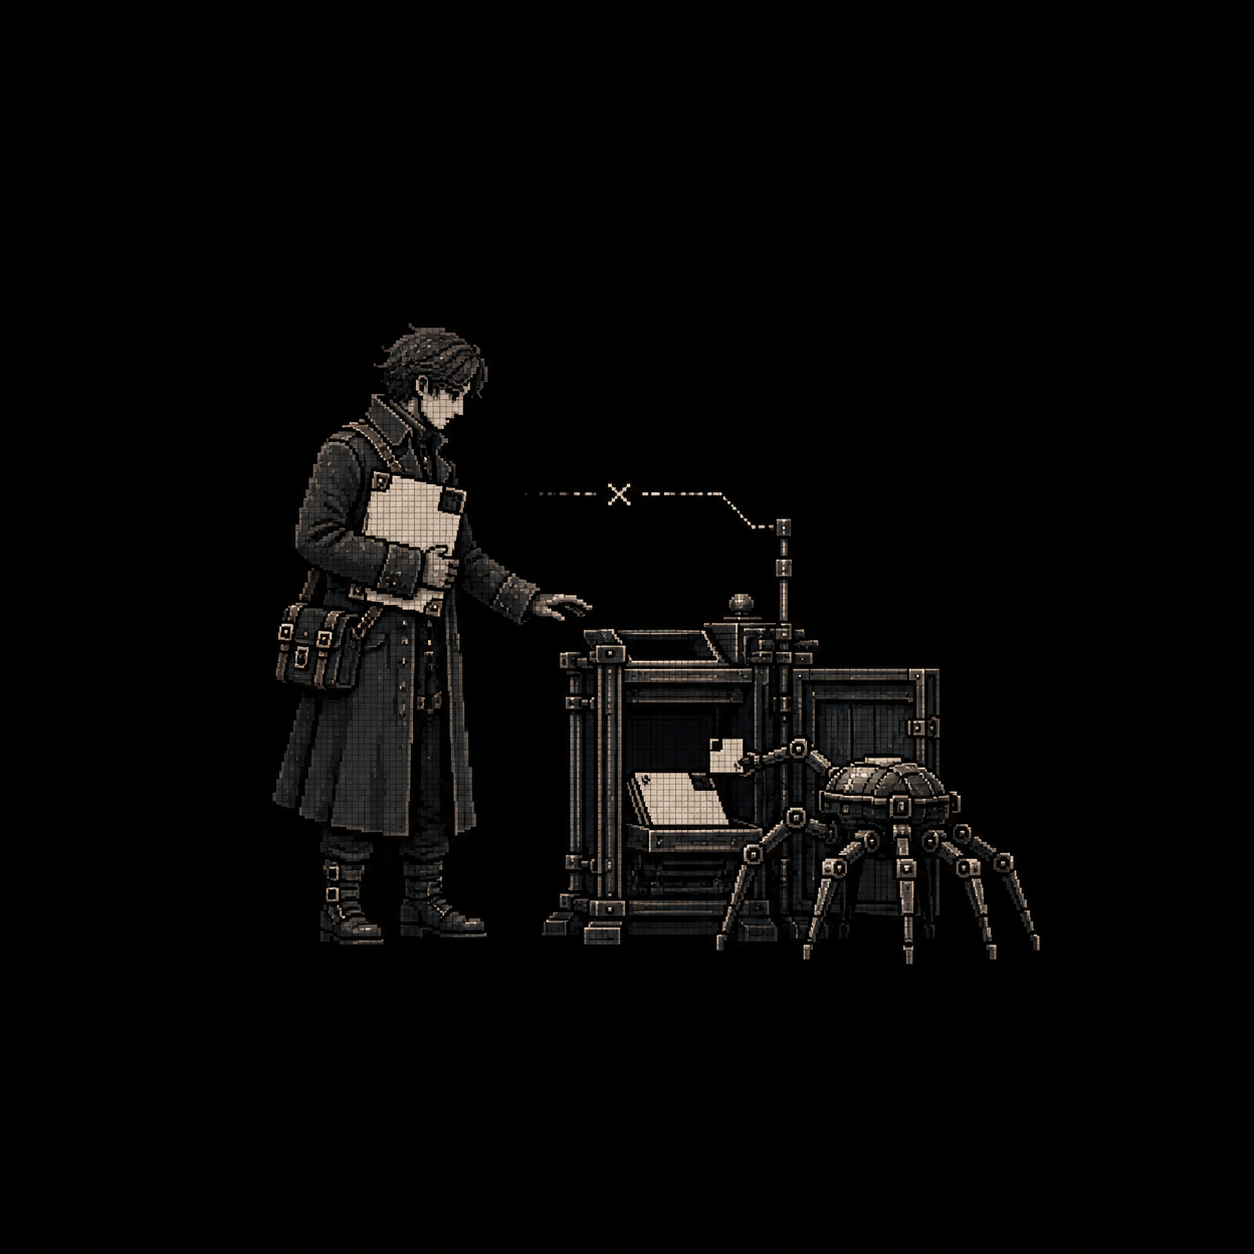
A request times out after an assistant uploads a file. The assistant can no longer see the response, but the receiving service may already have stored the upload. Clicking again can create a second copy. Waiting forever is also unsatisfactory when the task is unfinished and the user expects an answer.
The next operation should inspect the receiving system. That is the recovery rule specified in the action-ledger design for Boris, a native agent interface, which requires reconciliation before retrying interrupted mutations. The source describes intended behavior for sends, uploads, commits, saves, and form submissions. It does not supply a completed integration test proving that every operation follows the rule.
The difficult state is uncertainty after dispatch. An error before dispatch may establish that no request was sent. A lost response after dispatch establishes much less. Treating both cases as an ordinary retryable error removes precisely the distinction needed to avoid duplicate effects.
Did the destination receive the upload?
Suppose a user authorizes uploading one approved document to a particular project folder. The workflow records the document hash, destination identity, and action identifier before dispatch. In this instructional example, which is not a report from the Boris implementation, the service accepts the request and stores the document, but the connection closes before the assistant receives confirmation, leaving the caller with less information than the target system holds.
On recovery, inspect the destination using a read operation. Look for the service’s receipt identifier if one was retained. Otherwise compare available identity information, including the intended folder, document version, uploader, and creation interval. A matching filename is weak evidence when several drafts can share that name.
If a uniquely matching artifact exists, record the successful effect and attach the observation. If reliable inspection establishes that no upload occurred, the original authorized action may be retried within its scope. If the evidence cannot distinguish a previous upload from another user’s file, preserve the ambiguity in the action record and request the smallest decision needed before another mutation, including enough of the destination evidence for the user to understand what remains uncertain.
The workflow should not rename an unrelated file or delete a suspected duplicate as an improvised cleanup. Those are new effects with their own consequences. Recovery should establish the original request’s status before expanding the operation into a repair of the surrounding folder.
Does the service recognize a repeated operation?
Some services accept an idempotency key, an identifier that lets repeated requests represent one intended operation. Where the service contract supports it, keep the same key across attempts of that operation. Generating a new key for each retry can defeat the protection by telling the service that each attempt is a different request.
The key still requires a defined scope and lifecycle. Find out which endpoint honors it, how long the service retains it, and what happens if the same key arrives with different content. The runtime should preserve the original request data so a retry cannot accidentally change the upload while claiming the identity of the earlier operation.
When a service lacks this protection, reconciliation becomes more important. It may remain impossible to guarantee a single effect under every failure condition. Record that limitation at the operation level and use a human decision where the cost of a duplicate warrants it, rather than advertising a general guarantee that the surrounding system cannot support.
Can the recovery test distinguish both outcomes?
A normal upload test exercises the easiest route. For recovery, arrange a controlled target that commits the artifact and then withholds its response, after which you can restart the caller and verify that its first relevant operation inspects the destination rather than issuing another upload under a new attempt identifier. Count artifacts at the destination, rather than relying only on the caller’s success log.
Also test the opposite case, where the connection closes before the target stores anything. The workflow should eventually complete the authorized upload after establishing the absence of the first effect. A recovery procedure that prevents all duplication by never resuming any interrupted task has not met the completion requirement.
Preserve the action history through both exercises. The record should show the original dispatch, ambiguous outcome, inspection, and resulting decision. If target inspection is temporarily unavailable, retain a waiting or blocked state with the exact reason. For the document upload, completion requires one identified target artifact matching the approved source and a receipt that explains how its existence was established.
Source notes
Based on Boris’s specified side-effect recovery requirements. The upload and controlled-service tests are illustrative and do not report executed production behavior.