When a model connects but the tools fail
Separate the model’s answer from the software that has to carry out its requests.
A coding assistant can answer a question correctly and still fail as soon as it tries to open a file. The useful first question is where the requested action stopped. Changing the model before collecting that evidence can leave the actual fault untouched, particularly when several programs translate requests between the assistant and the tool.
In February 2026, I reported successfully connecting Codex through LiteLLM, software that translates model requests, to Claude Code, the application hosting the assistant. Four days later, I reported tool failures on ordinary requests and crashes on larger jobs. Those statements describe different observations. The connection worked well enough to establish configuration success; the later failures left reliable operation unresolved. The surviving record does not establish a successful repair.
A model produces requests and responses. The runtime is the surrounding software that manages those requests, invokes tools, preserves their results, and decides what happens next. A proxy may translate one provider’s message format into another. The application running the assistant may impose another contract on that translation. Each boundary needs its own evidence.
Follow one request through the system
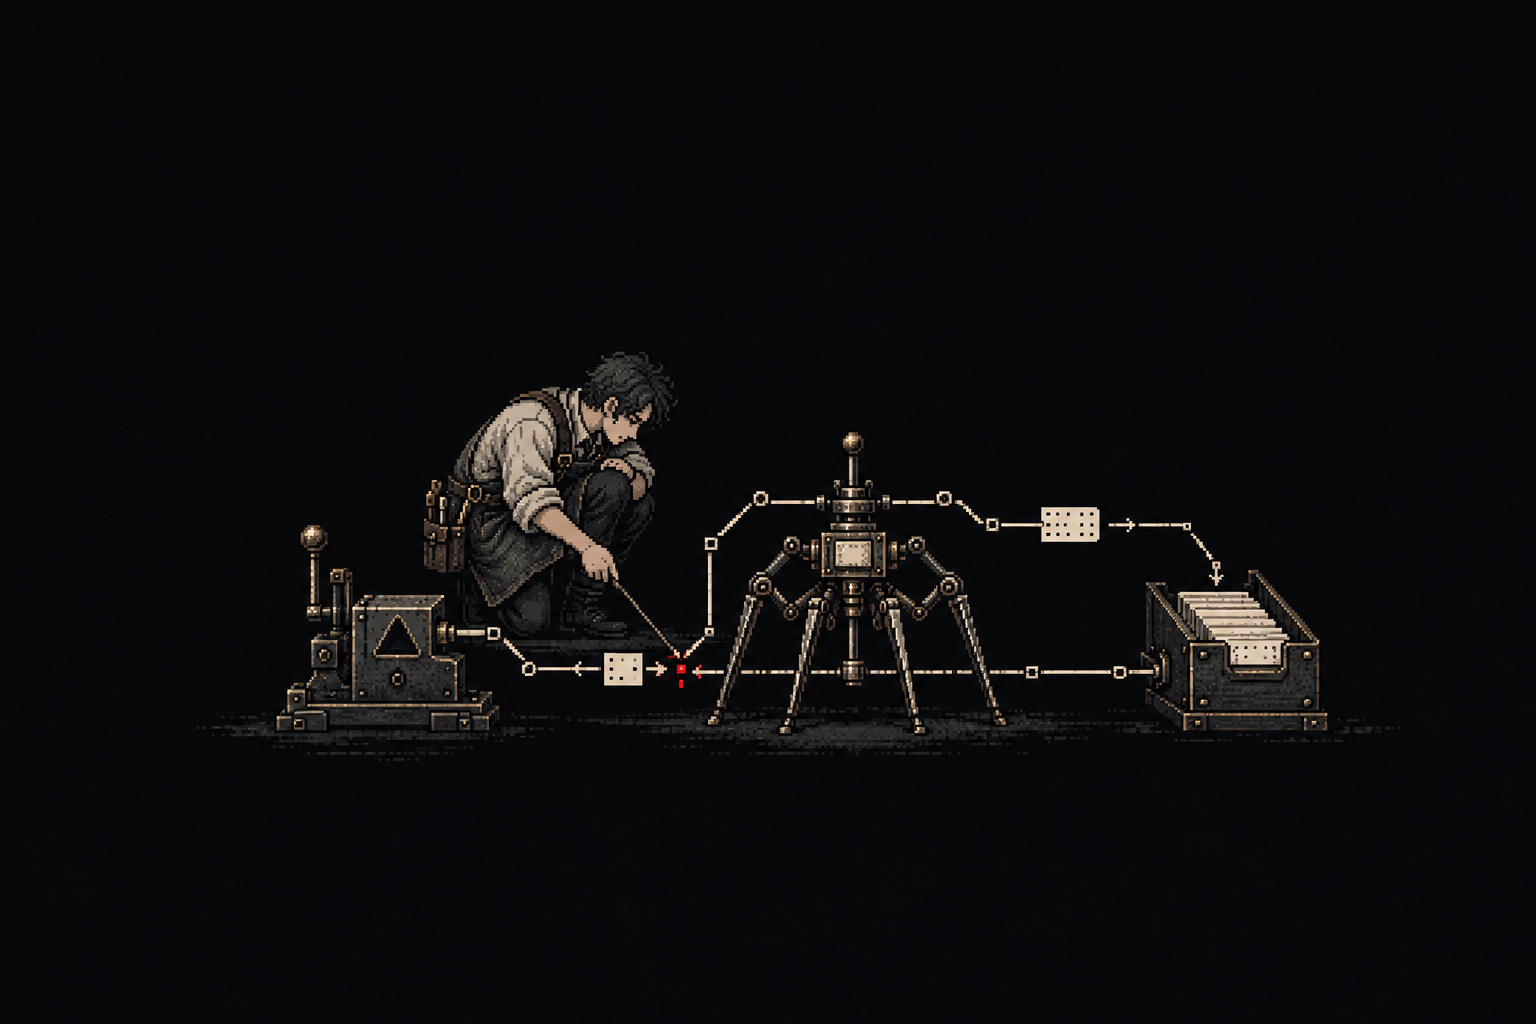
Start with the smallest task that includes a real tool call, asking the assistant to read a harmless fixture file containing a known sentence so that a successful execution has an expected result you can compare with the response the host actually receives. Preserve the request as it leaves the host, its translated form, the model’s returned tool request, the tool’s actual invocation, and the result delivered back to the model. Remove credentials and private content from any diagnostic copies.
This sequence gives the investigation a specific object. If the model requests a nonexistent tool, inspect the advertised tool names and returned request. If the tool executes but the host rejects its result, inspect the result format and correlation identifier. If the host waits forever after receiving a complete result, inspect its state transition. The visible symptom may be the same spinning interface.
In this illustrative example, which does not reconstruct my crash, a host advertises a file-reading tool and the model requests it with an identifier, after which the proxy delivers a valid request to an executor that returns the expected fixture text without an error. On the return route, the proxy changes the identifier. The host cannot associate the result with the pending request, so the next turn stalls despite a successful file read.
Replacing the file-reading implementation would accomplish little in this example. The missing evidence sits between successful execution and result acceptance. Preserve both identifiers and write a test that asserts their relationship across the translation. The test should fail on the broken mapping before a proposed repair is accepted.
Increase the workload deliberately
A single read cannot establish long-job reliability. Once that operation works, add a second sequential call, then a mixed read-and-write task in a disposable directory. Test errors deliberately. Request a missing file and check whether the runtime returns an intelligible failure without corrupting the next action.
Then increase output size and duration separately. A large tool result tests buffering and message limits; a slow tool tests timeouts and cancellation. Combining both changes immediately makes the result harder to interpret. Record the input size, elapsed time, environment version, and last completed boundary for each run, preserving the successful trace alongside the failed one so a later investigation can compare the same sequence under the conditions that actually differed.
Streaming deserves its own case. A partial argument fragment is not necessarily an executable request. The host must know when the request is complete, how cancellation affects buffered fragments, and whether a tool can still be running after the interface stops displaying activity. Test those conditions with a controlled tool whose completion can be observed independently.
Keep the diagnosis narrower than the symptom
The historical reports establish failures, not their precise cause. A malformed tool envelope, a runtime defect, and a resource limit remain different hypotheses until a trace or reproduction distinguishes them. Calling all three “the model failed” discards the information needed to choose a repair.
A useful incident report therefore ends with a reproducible operation and a located failure boundary. Include the last known-good event, the first missing or malformed event, and the smallest test that reproduces the gap. If no such test exists yet, retain the competing explanations and collect the next trace. After a repair, rerun that fixture and the longer sequence before describing the integration as reliable.
Source notes
Based on my February 2026 configuration and failure reports. The diagnostic example is illustrative; the record does not verify the failure’s cause or a completed repair.