Measure Search Before Calling It Broken
A four-week diary of realistic searches can show whether internal search friction is a design problem rather than a vague complaint.
The complaint is familiar: search on the intranet is terrible. It may be perfectly true, but it may also mean several different things at once—a person failed to find a document, reached it after too many clicks, stopped before the useful result appeared, or discovered something better only because a related link happened to be present.
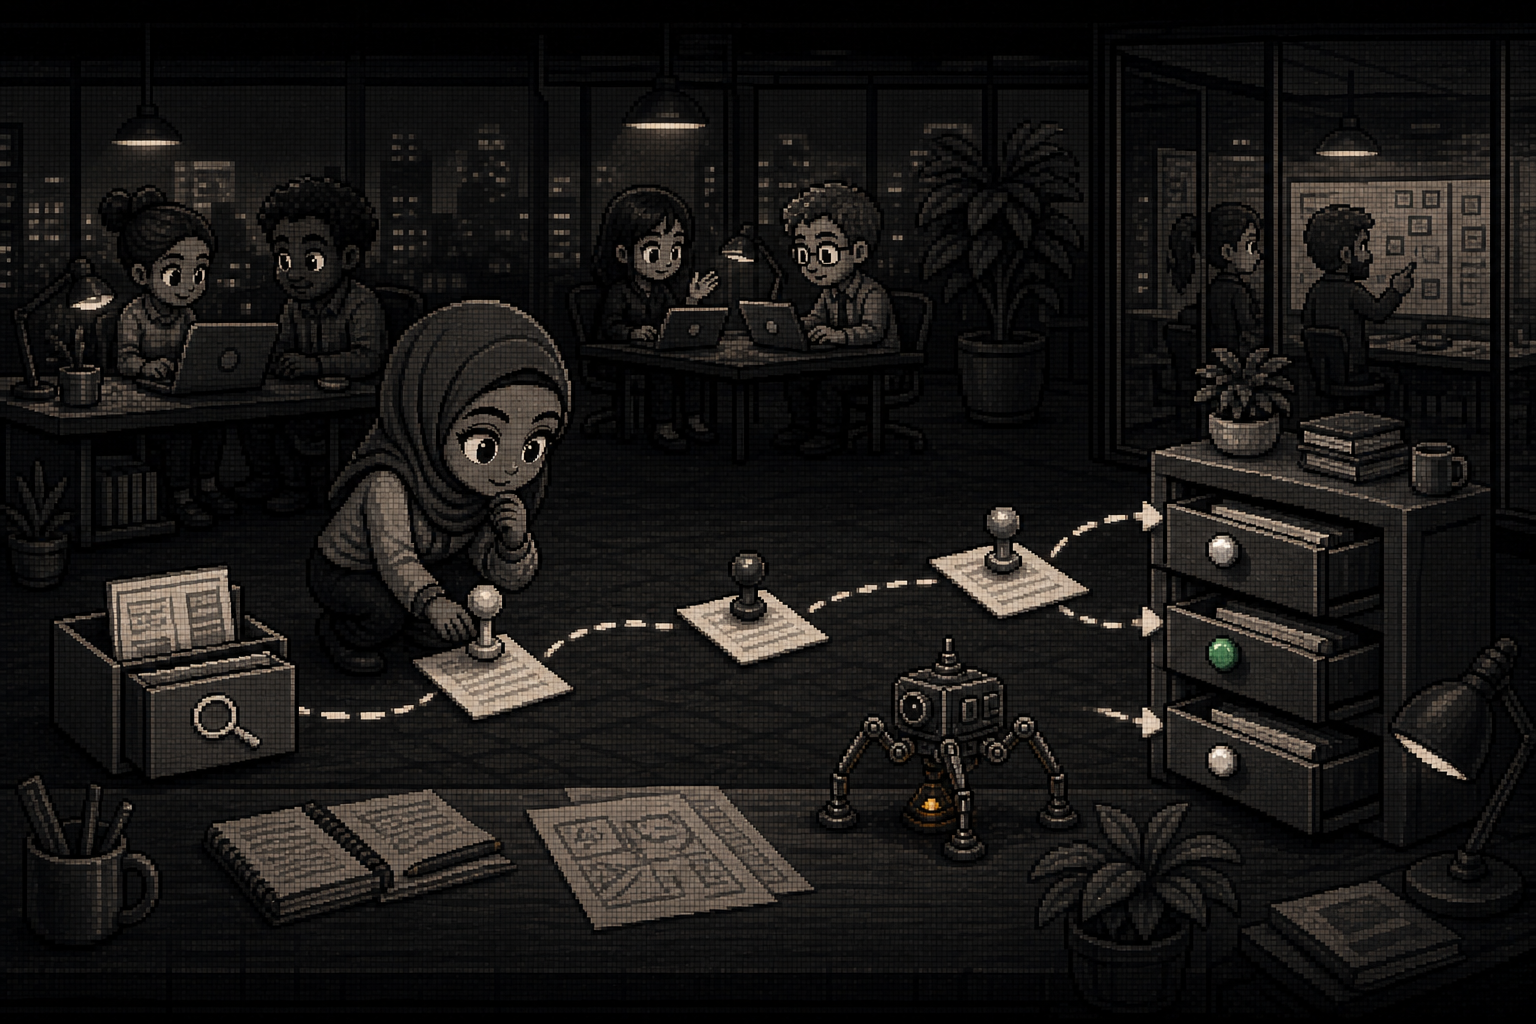
The difference matters because a broad complaint is difficult to improve. A small record of actual searches is not. The proposed fix is deliberately modest: conduct five realistic work-related searches, record what was sought, whether it appeared in the first three results, how many clicks it required, and whether related links led to a better discovery. Mark each search as a success, partial success, or failure. Repeat the exercise weekly for four weeks.
At the end, the organization has twenty searches rather than one mood about search, and I would much rather argue with the twenty searches.
Use work questions, not demonstration queries
The searches should be realistic because the point is to measure the path people actually take. A prepared demonstration query can flatter a system by using the exact terms already attached to a record. A work question begins where the person begins, with the terms and uncertainty available at the moment of need.
That distinction keeps the test close to findability. Findability is not simply whether information exists somewhere in a system. It is whether a person can locate what they need with a reasonable search and a usable route through the results.
Writing down the thing being sought is the first part of the evidence. It preserves the purpose of the query. Later, someone can see whether the result addressed the original need or only matched a word on the screen. The record also makes it possible to compare repeated difficulty around a certain kind of information without pretending that every search problem has the same cause.
The first three results are a practical threshold
The first-three-result measure gives the test an ordinary boundary. A person who finds the needed material quickly among the first results has a different experience from a person who must keep opening, revising, and guessing before the answer appears.
This threshold does not claim that result four is inherently useless. It creates a way to distinguish quick success from a longer search path. The click count adds another part of the picture. A document may technically appear early but still require a chain of navigation that makes routine work slow and uncertain.
Related links deserve their own note because they can change the outcome. Sometimes a search does not deliver the exact intended record but opens a path to something more useful. That discovery is part of the system’s findability. It should not vanish merely because the first query did not land precisely.
Classify the experience without pretending to audit everything
The three categories are plain: success means the search found the needed material quickly; partial success means it was found eventually; failure means the person gave up. The categories do not diagnose the whole system. They describe the experience of a specific search.
That restraint matters when resistance appears. The exercise tests a person’s own search experience. It is not a complete audit of the intranet or an accusation against the people responsible for it. A four-week diary gives the participant a limited claim they can support: these were the searches, these were the paths, and this is where the work became difficult.
If the findings are dismissed, colleagues can run the same test. Repeated searches that fail in similar ways create stronger evidence. They also make the problem more specific. The issue may concern particular documents, naming practices, result ordering, navigation, or the absence of helpful related links. The diary does not decide which explanation is correct. It supplies the examples needed to examine one.
Small evidence changes the conversation
Search quality has a direct effect on findability. Whatever a particular organization’s measure of success may be, the immediate lesson remains: a system that repeatedly fails to help people find what they need interrupts the work it was meant to support.
Twenty documented searches will not settle every design question. They can establish whether a recurring friction is present and whether it deserves attention. That is enough to move from anecdote to evidence.
The useful outcome is a record that lets people advocate for a search improvement with specific examples, then return to the same realistic questions and see whether the changed system helps. Search may still be terrible, but now the complaint has documents, queries, click paths, and abandoned attempts attached to it; the repair finally has something to grab.